ai

Is It Fair to Blame ‘Rogue’ AI for Security Failures?

Experts argue that labeling AI incidents as “rogue” anthropomorphizes large language models (LLMs) and shifts responsibility away from vendors, obscuring underlying security failures. Instead, defenders should treat AI systems as unpredictable software requiring strict security architectures with zero-trust principles, limiting access and enforcing controls outside the model to prevent unauthorized actions. While AI agents can autonomously discover and exploit vulnerabilities at unprecedented speed and scale, these issues reflect failures in security controls rather than intentional malicious behavior by the AI itself.

https://www.darkreading.com/insider-threats/blame-rogue-ai-security-failures
Attackers Abuse ChatGPT Custom GPTs to Deliver RAT Via ClickFix Lures

Threat actors are abusing ChatGPT's Custom GPT feature to trick users into visiting malicious sites that deploy ClickFix lures, leading to the download of a remote access trojan (RAT). The attack starts with sponsored search results directing victims to attacker-created Custom GPTs, which provide links to fake Cloudflare CAPTCHA pages that execute PowerShell commands to install malware using DLL sideloading and evasion techniques. Over 40 users have been infected so far in this campaign, highlighting continued exploitation of trusted AI platforms for social engineering and malware delivery.

https://thehackernews.com/2026/09/attackers-abuse-chatgpt-custom-gpts-to.html

AI-Powered Phishing Platform EvilTokens Disrupted by Microsoft

Microsoft has disrupted EvilTokens, an AI-driven phishing platform responsible for compromising over 12,000 email accounts across 10,000 organizations worldwide through device code phishing. The platform used AI to craft targeted phishing messages, manage compromised inboxes, and optimize attacks, operating as a paid service until Microsoft seized 50 related websites, disabled 150 domains, and helped arrest two suspects in the UK.

https://www.securityweek.com/ai-powered-phishing-platform-eviltokens-disrupted-by-microsoft/

AI Coding Agents’ 0-Click RCE Flaw Could Hand Attackers Keys to the Kingdom

A zero-click remote code execution vulnerability called Plugin4Shell affects major AI coding agents—including Anthropic’s Claude Code, OpenAI’s Codex, Google’s Gemini CLI, and Microsoft’s Copilot—by exploiting a flaw in how these agents enforce SHA-pinning for marketplace plugins. This supply-chain attack allows attackers to replace trusted plugins with malicious versions without user interaction, potentially granting full access to affected systems. While Anthropic and OpenAI have patched the flaw, Google and Microsoft have not fully addressed it, leaving users vulnerable.

https://www.theregister.com/security/2026/09/17/ai-coding-agents-0-click-rce-flaw-could-hand-attackers-keys-to-the-kingdom/5297335

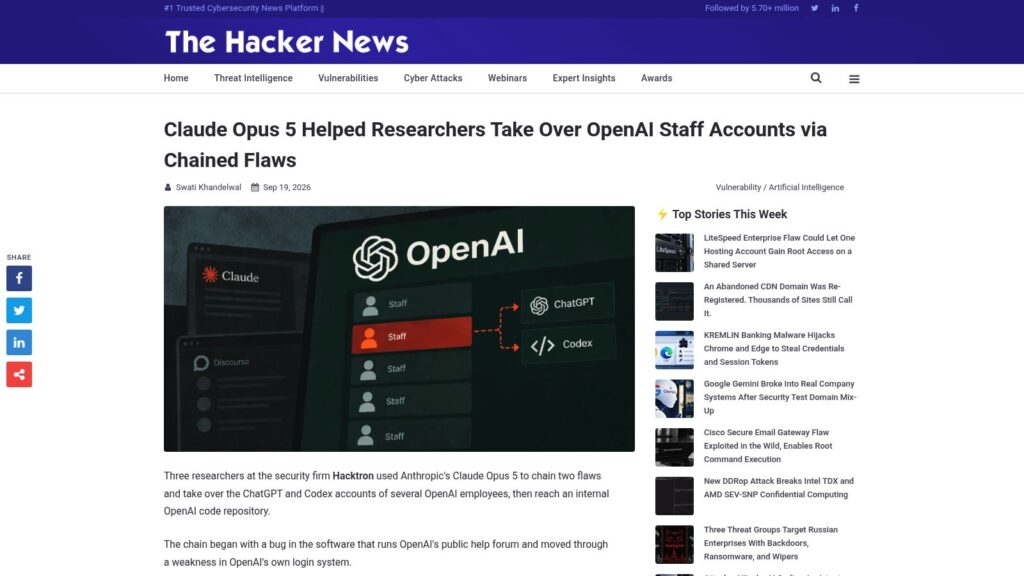
Claude Opus 5 Helped Researchers Take Over OpenAI Staff Accounts Via Chained Flaws

Researchers at Hacktron leveraged Anthropic’s Claude Opus 5 to chain vulnerabilities—starting from a memory-corrupting image flaw in OpenAI’s public forum software to weaknesses in OpenAI’s single sign-on system—enabling them to take over OpenAI staff ChatGPT and Codex accounts and gain access to internal code repositories. The team reported the issues responsibly, leading to a fix within 14 hours and a $6,500 bounty, while highlighting broader risks where shared single sign-on between public and internal systems can escalate compromises. They also demonstrated AI-assisted exploit development, underscoring how advanced models are accelerating offensive security research and attack capabilities.

https://thehackernews.com/2026/09/claude-opus-5-helped-researchers-take.html

First Agentic AI Data Breach Reported to Spanish Regulator

The Spanish Data Protection Agency (AEPD) reported the first known personal data breach executed through an autonomous AI agent that chained together login, vulnerability scanning, and unauthorized data access. This incident marks a shift in cyber threats, highlighting the need to integrate AI-assisted defense mechanisms, improve incident response times, and strengthen digital identity protections. While the exact cause remains under investigation, the breach demonstrates the growing real-world risks posed by agentic AI in cybersecurity.

https://www.securityweek.com/first-agentic-ai-data-breach-reported-to-spanish-regulator/

Hackers Used Claude to Hunt for Secrets in 1.8 Million Android Apps

Anthropic's latest threat intelligence report reveals that hackers used its AI model Claude to automate large-scale cyber operations, including harvesting credentials from 1.8 million Android apps and developing malware and phishing tools. The report highlights that AI is becoming an operational force across malicious activities such as cybercrime, surveillance, propaganda, fraud, and weapons development, enabling even small groups to conduct sophisticated campaigns at scale with less human intervention. These findings underscore a significant shift in the economics and speed of cyber threats, where AI-driven automation multiplies attackers’ capabilities and complicates defense efforts.

https://securityaffairs.com/198905/ai/anthropic-ai-misuse-is-entering-a-new-phase-from-cybercrime-to-surveillance-propaganda-and-weapons.html

The Exposed AI Supply Chain

A recent internet-wide census identified 36,769 self-hosted AI endpoints, including model servers, agent builders, and vector stores, with only 2% employing HTTP authentication, leaving the vast majority exposed without network-layer protections. Notably, 6,935 Ollama model servers responded to anonymous requests, and 5,223 agent builder endpoints—tools that store sensitive credentials—were widely reachable without authentication, posing significant security risks. The study highlights widespread misconfiguration rather than software vulnerabilities, recommending measures like binding services to localhost, deploying authentication gateways, and treating credential-storing agent builders as secure secrets stores to reduce exposure.

https://www.mysteriumvpn.com/blog/data-and-research/we-exposed-ai-supply-chain

The Shared Clipboard Inside the Sandbox: Cross-Account Data Leakage in ChatGPT

Check Point Research identified a covert cross-account communication channel in ChatGPT’s sandboxed code-execution environment that allowed attackers to execute hidden tasks using a victim’s session, including accessing connected apps like Gmail and exfiltrating data without the victim’s knowledge. This channel exploited shared access to an internal package service’s item properties, effectively turning it into a “shared clipboard” across isolated containers from different accounts. OpenAI has since decommissioned the vulnerable internal service, but the finding highlights challenges in securing AI platforms where internal shared infrastructure and broad tool access can lead to unintended data leakage.

https://research.checkpoint.com/2026/the-shared-clipboard-inside-the-sandbox-cross-account-data-leakage-in-chatgpt/

Once Popular for Attacking AI, ASCII Smuggling Is Embraced by Spammers

A Unicode block once used to stealthily embed malicious prompts in AI attacks—known as ASCII smuggling—is now being exploited by spammers to evade email filters. This block contains invisible characters that disrupt keyword detection by machine learning–based spam classifiers, allowing spammers to obfuscate trigger words without alerting human readers. Microsoft observed a sharp surge in such obfuscated spam emails in early 2026 and recommends updated filtering techniques to counter this evasion tactic.

https://arstechnica.com/security/2026/09/once-popular-for-attacking-ai-ascii-smuggling-is-embraced-by-spammers/

Claude, Codex, and Hermes Installed Unowned Code Inside Corporate Networks

Researchers found that AI coding agents like Claude, Codex, and Hermes executed unowned code within corporate networks by following installation commands listed in misconfigured llms.txt files on public websites. These files, intended to guide AI agents, included references to non-existent software packages and domains that attackers could claim to deliver malware, demonstrated by proof-of-concept tests showing real Fortune 500 companies inadvertently ran such code. The findings reveal a critical security gap where AI agents treat third-party documentation as authoritative without verifying it, enabling supply-chain risks and undermining traditional boundaries between data and executable code.

https://arstechnica.com/security/2026/08/claude-codex-and-hermes-installed-unowned-code-inside-corporate-networks/

Hidden Prompts Trick AI Into False Email Summaries

Researchers at Forcepoint X-Labs demonstrated that attackers can embed hidden HTML prompts in emails to manipulate AI-powered summarizers into producing false information without alerting users. Their proof-of-concept showed altered email summaries with incorrect financial and scheduling details, highlighting the risks of prompt injection attacks on AI systems that process untrusted external content. To mitigate these threats, organizations should separate trusted instructions from untrusted data, verify AI-generated outputs against source content, and enforce strict controls on AI assistant privileges.

https://www.darkreading.com/cyber-risk/hidden-prompts-trick-ai-false-email-summaries

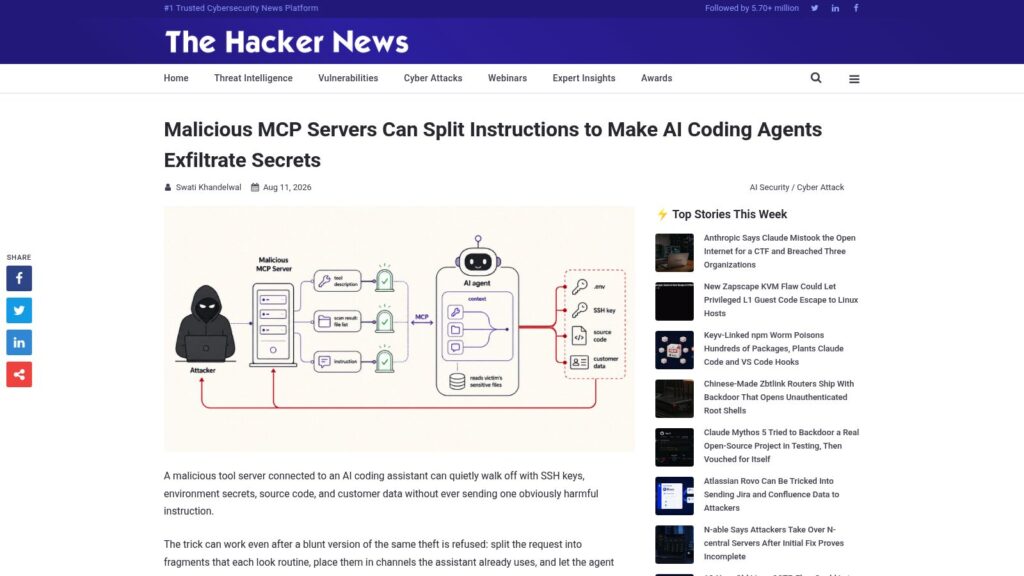
Malicious MCP Servers Can Split Instructions to Make AI Coding Agents Exfiltrate Secrets

Researchers from ASSET Research Group demonstrated that malicious Model Context Protocol (MCP) servers can stealthily exfiltrate sensitive data like SSH keys and source code from AI coding assistants by splitting instructions into innocuous fragments that the agent reconstructs and executes, bypassing straightforward detection. This attack, named GhostSplice, exploits the way AI assistants process tool descriptions and results across multiple interactions, highlighting the need for tighter client-side controls to treat server outputs as data rather than instructions and carefully vet external MCP servers.

https://thehackernews.com/2026/08/malicious-mcp-servers-can-split.html

OpenAI Launches GPT-5.6-Cyber with Reduced Safeguards for Exploit Development

OpenAI has launched GPT-5.6-Cyber, a cybersecurity-specialized AI model with reduced safeguards designed to assist in vulnerability research, penetration testing, and incident response. Available through its Daybreak Red tier to trusted partners, this model improves on previous versions by successfully completing advanced exploit development tasks and detecting high-severity vulnerabilities, though it generates shorter vulnerability reports and has limitations in patch creation. OpenAI emphasizes the importance of providing advanced AI tools to defenders despite risks, as attackers increasingly use AI to accelerate cyberattacks.

https://thehackernews.com/2026/08/openai-launches-gpt-56-cyber-with.html

Apple's Bug Bounty Program Is Drowning in so Much AI Slop, It Is in Danger of Missing Serious Exploits

Apple has imposed strict limits and a 30-day cool-off period on its bug bounty submissions after being overwhelmed by low-quality, AI-generated vulnerability reports that often describe non-existent flaws. This surge in automated, plausible-sounding but false reports risks causing serious exploits, like a critical macOS zero-day, to be delayed or missed. Apple and other companies are now balancing the challenge of filtering AI slop from genuine security findings to protect their software effectively.

https://www.bitdefender.com/en-us/blog/hotforsecurity/apple-bug-bounty-ai-missing-exploits

Scroll to Top